LLM Inference Repository
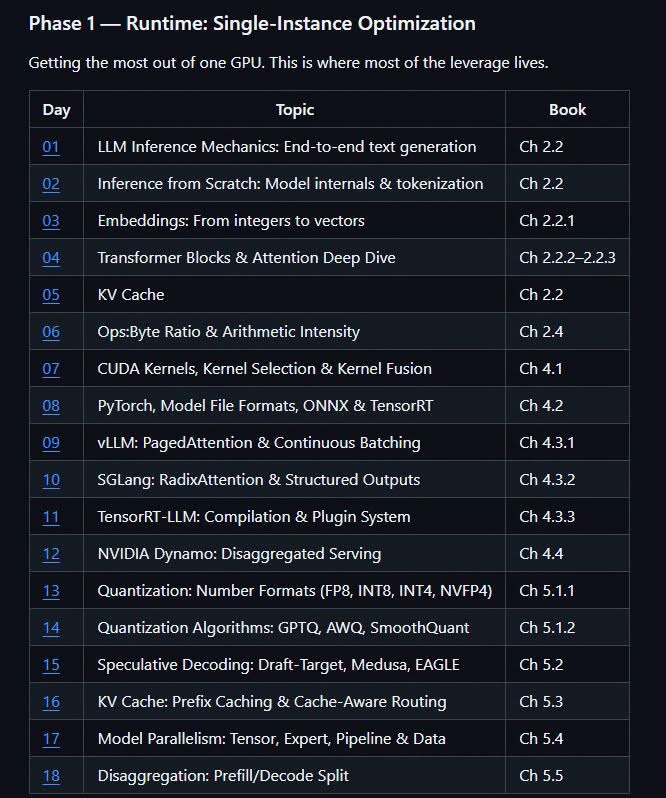
The open-source collection 100 Days of LLM Inference offers a hands-on pathway for engineers and researchers who want to master large-language-model inference. Structured as a series of daily notebooks, the repository walks readers from low-level CUDA kernel implementations all the way to production-grade serving stacks.
Topics span the full inference stack: starting with custom CUDA kernels, then exploring high-performance serving frameworks such as vLLM, SGLang, and TensorRT-LLM. Later sections dive into model compression techniques like quantization, advanced generation strategies such as speculative decoding, and finally multi-cloud autoscaling patterns for scalable deployments.
Every notebook is executable out-of-the-box and has been validated on a dual-GPU testbed, ensuring that the examples run reliably on real hardware. This practical verification makes the repo a solid reference for anyone looking to see how LLMs are truly deployed and tuned for performance.
References
These external sources were used to verify the article and provide deeper context.
Conclusion
For developers seeking a comprehensive, tested guide to LLM inference optimization, the LLM Inference Repository 100 Days of LLM Inference is a highly recommended resource. Its step-by-step notebooks and coverage of both low-level and high-level techniques provide a clear view of real-world deployment workflows.