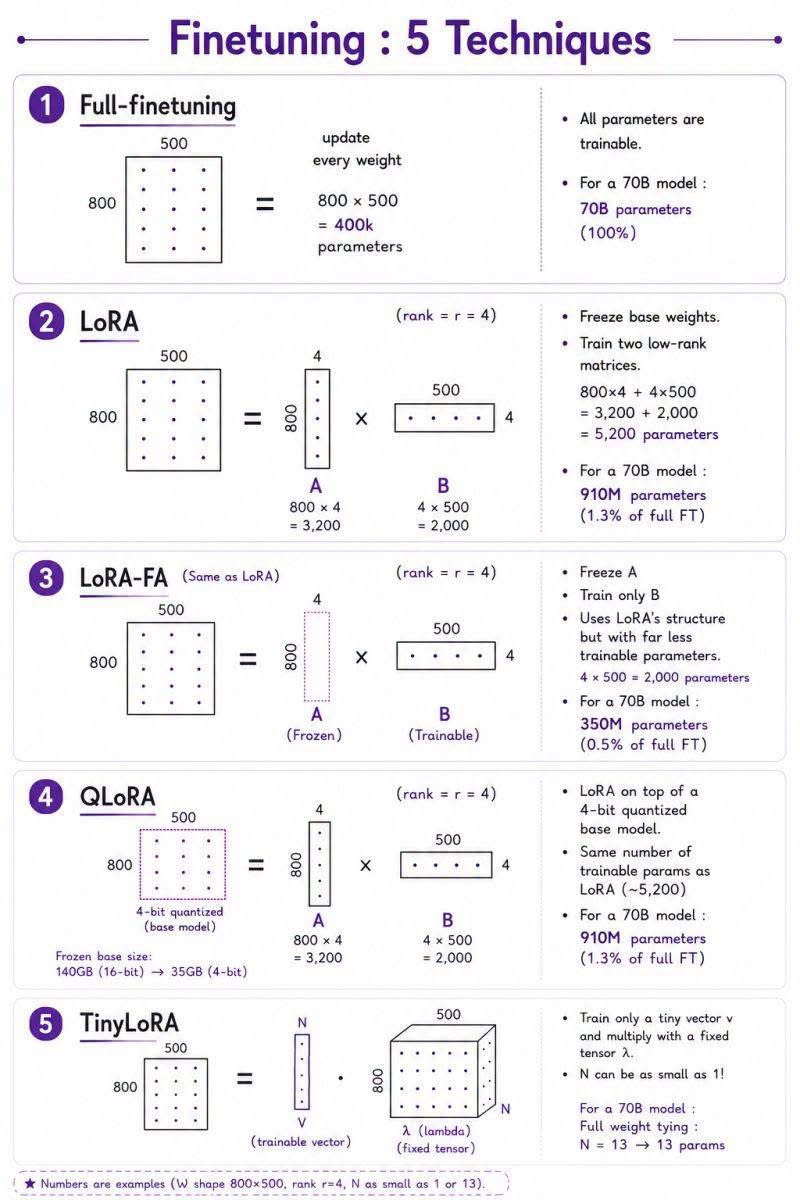
"To fine-tune a 70B model, you don't need to train all 70 billion parameters." This statement might sound counterintuitive, yet it perfectly encapsulates the current paradigm for fine-tuning large language models (LLMs). This revolutionary approach is known as Parameter-Efficient Fine-Tuning (PEFT), and it's transforming how developers and researchers interact with massive AI models.
Imagine fine-tuning an LLM as updating a comprehensive book. The evolution of fine-tuning methods reflects a clear progression towards efficiency:
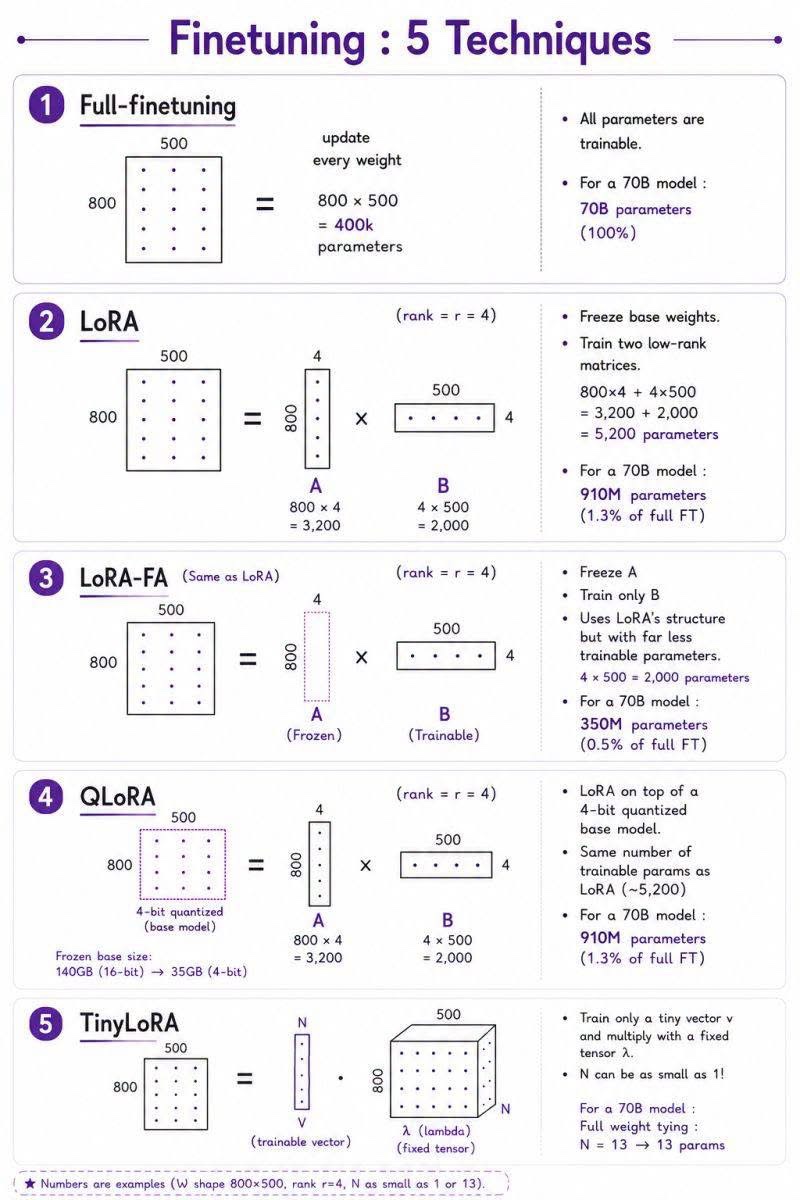
- Full Fine-tuning: This is akin to rewriting the entire book from scratch, adjusting every single word and sentence. While thorough, it's resource-intensive.
- LoRA (Low-Rank Adaptation): Instead of rewriting, LoRA keeps the original book intact and only adds a set of “smart notes” or small, trainable matrices (adapters) to guide the model's behavior.
- LoRA-FA (LoRA with Frozen Adapters): Building on LoRA, this method further freezes a portion of the adapter parameters, reducing the number of parameters that need to be learned even more.
- QLoRA (Quantized LoRA): This technique drastically reduces memory requirements by storing the original model in a highly compressed 4-bit quantized format, making large models accessible on more modest hardware.
- TinyLoRA: Pushing efficiency to its extreme, TinyLoRA learns only a very small vector, sometimes involving just a few parameters in certain cases, offering ultra-lightweight adaptation.
This progression reveals a clear trend in AI development: from training the entire model, to learning only the necessary changes, then compressing the model, and finally, retaining only what is truly essential. This paradigm shift underscores a critical insight: major advancements in AI don't always come from making models larger. Often, the more impactful breakthroughs stem from training less while still achieving nearly equivalent performance. This is the core strength and practical value of Parameter-Efficient Fine-Tuning.
References
These external sources were used to verify the article and provide deeper context.
Nguồn hình ảnh
Phần kết luận
The evolution of fine-tuning techniques, particularly Parameter-Efficient Fine-Tuning, demonstrates a powerful shift towards smarter, more resource-efficient AI development. By focusing on adapting only a fraction of a model's parameters, we can achieve significant performance gains without the prohibitive costs of full retraining.