The Jev decision layer improves hybrid Retrieval-Augmented Generation (RAG) by addressing a common shortcoming: vector search often returns passages that look similar to the query but may not actually answer it.
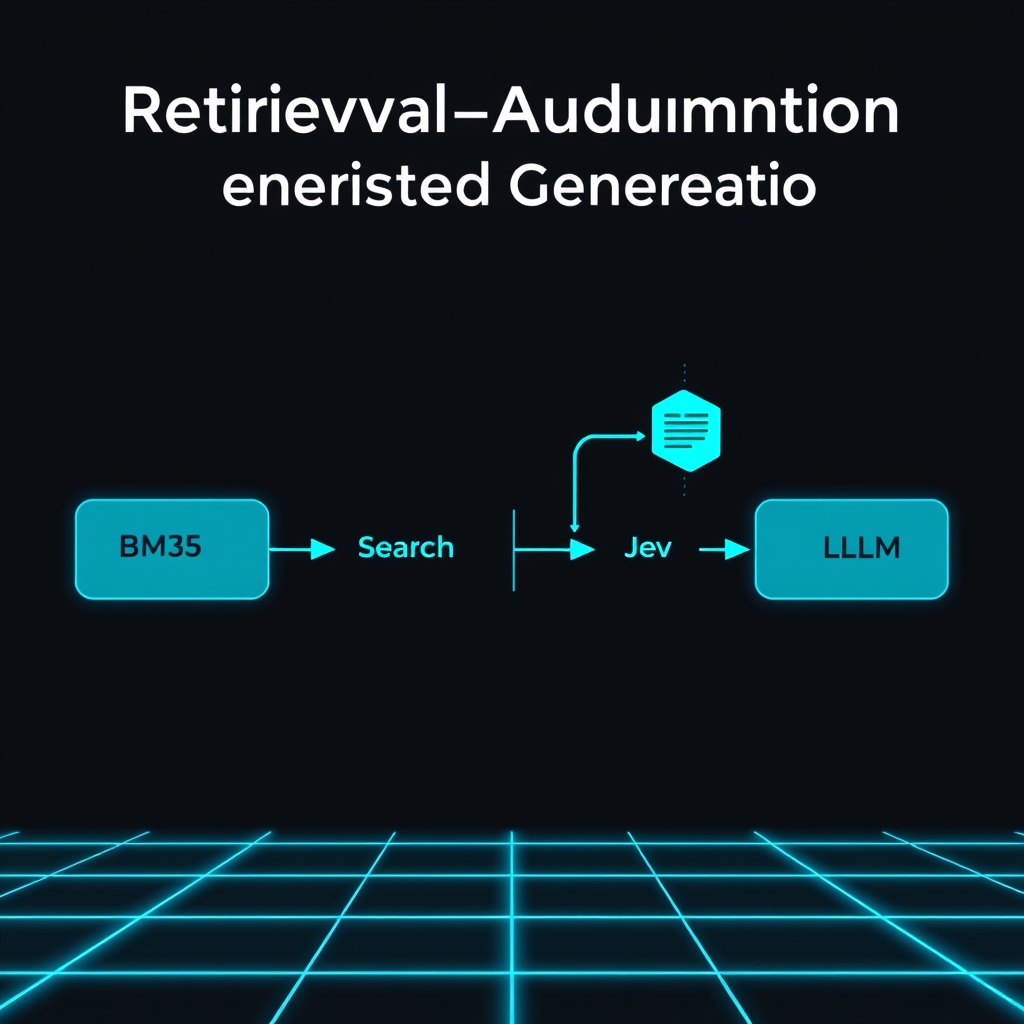
In the proposed architecture, BM25 and vector search first retrieve candidate chunks. Those candidates are then passed to Jev, which acts as a classifier to decide whether each chunk truly answers the question. Only the verified chunks are handed to a large language model (LLM) for answer generation. The flow can be summarized as: BM25 + Vector Search → Jev classifies → LLM generates the answer.
Experimental results show that Jev reaches relevance-evaluation accuracy on par with frontier LLMs while incurring roughly one-twentieth of the cost and eliminating near-miss errors. This demonstrates the core idea of assigning classification to Jev and generation to the LLM, letting each model play to its strengths.
The approach is especially promising for production-grade RAG systems where both precision and expense are critical factors.
Phần kết luận
Deploying the Jev decision layer in hybrid RAG pipelines delivers frontier-level relevance at a fraction of the cost, making it a compelling strategy for scalable AI applications.